Data engineering infrastructure, rebuilt the simple way
LongData takes the complex, error-prone mechanisms into the system, leaves a simple, well-defined and verifiable surface to work on, and proves every result with deterministic verification that is independent of the agent. The design choices that make an engineer's work simple are exactly the working environment an agent needs.
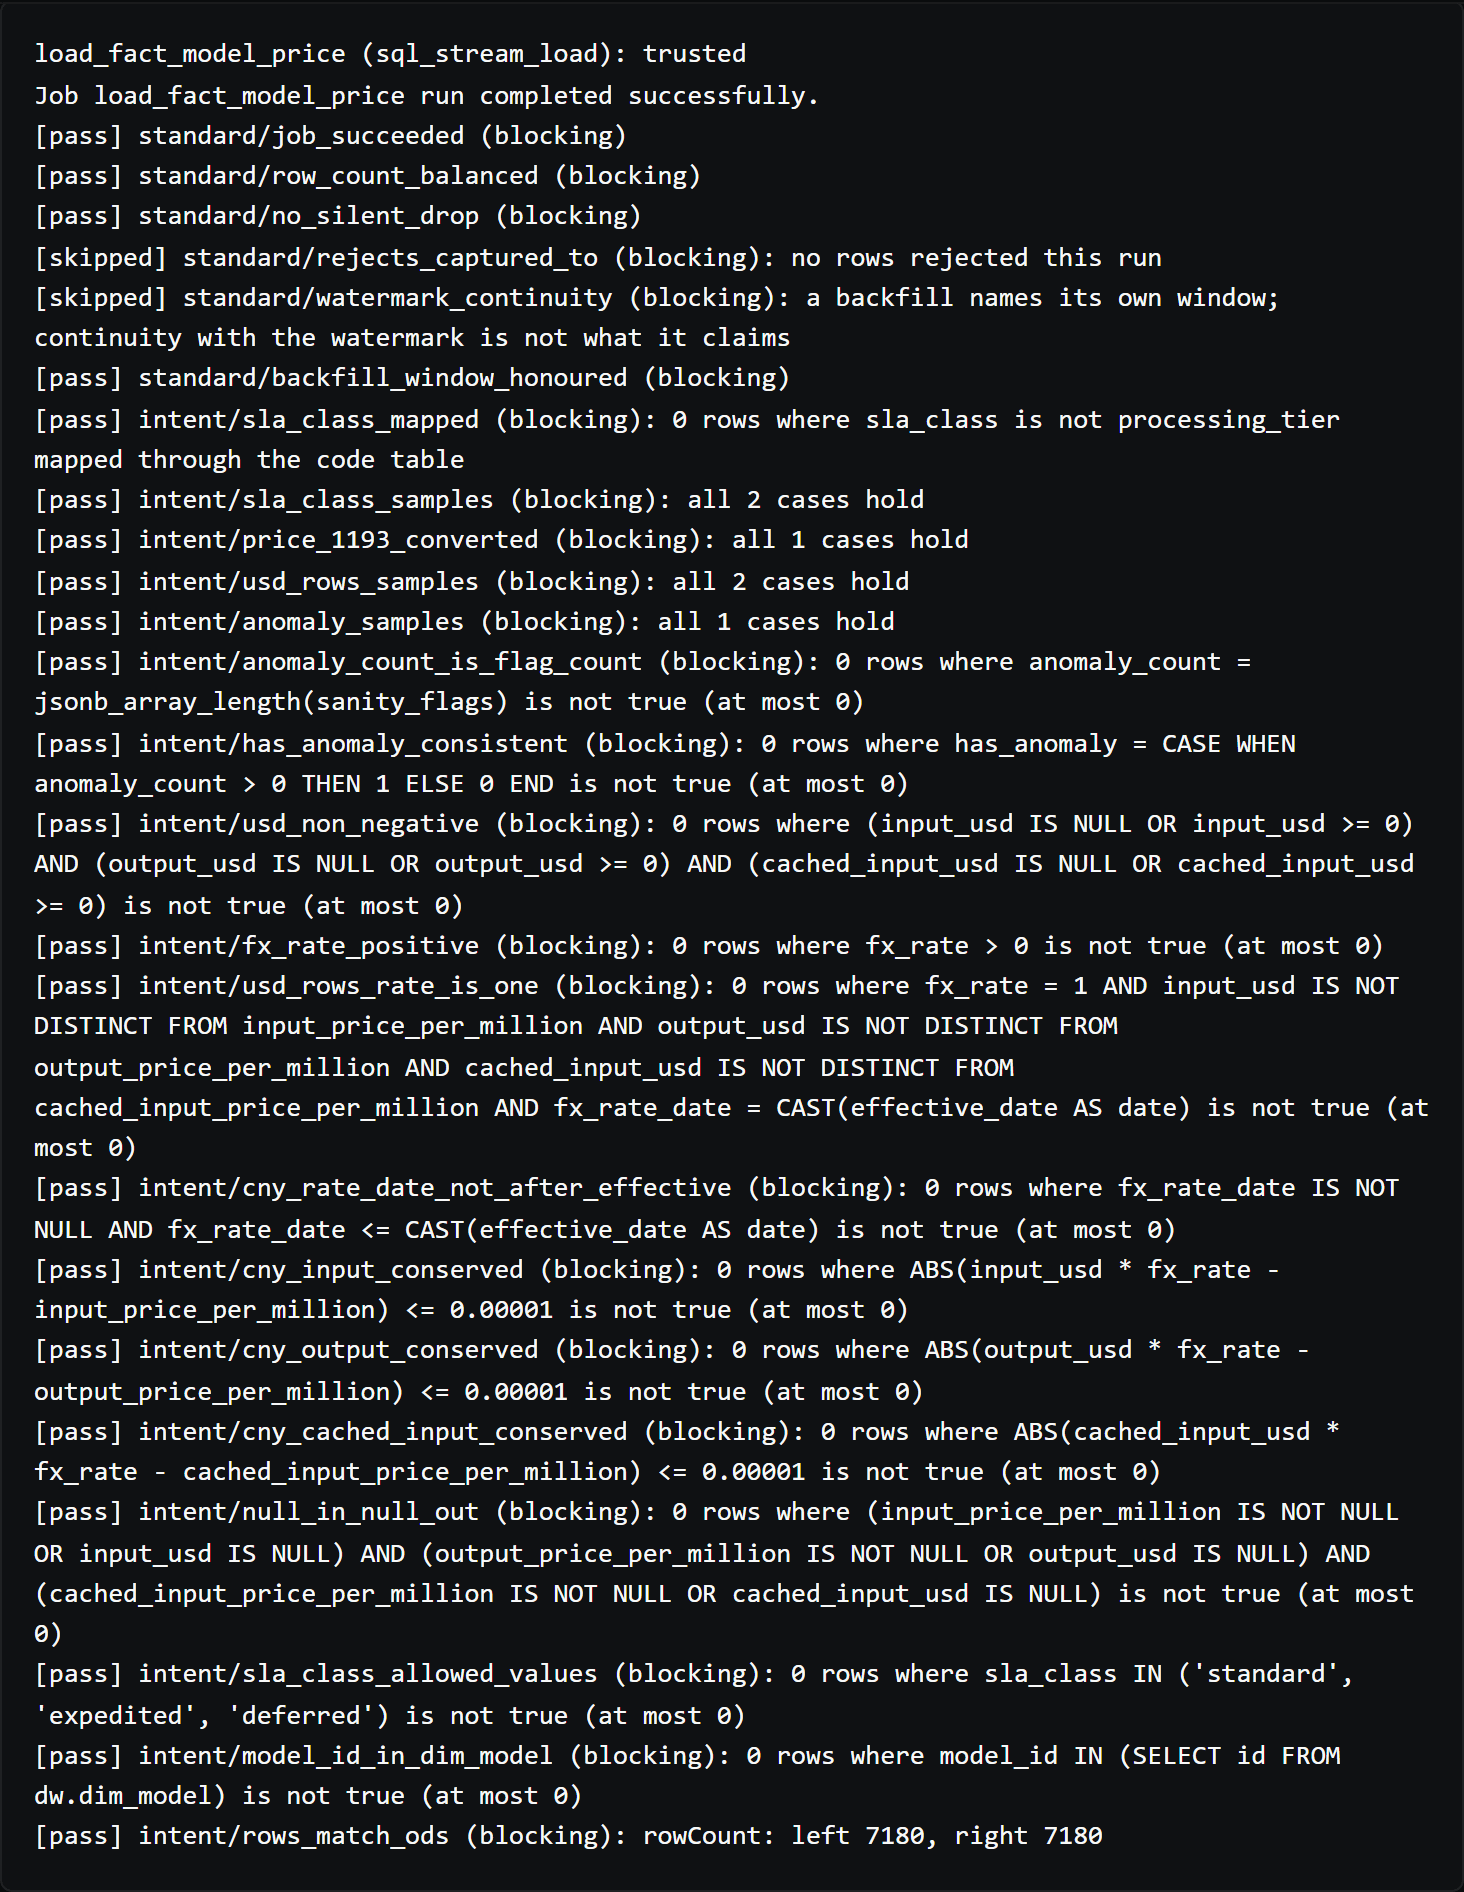
A real run of a job the agent wrote: the platform's verdict on every run guarantee and acceptance clause.
Where the industry stands
Data engineering is entering the age of agents
Data engineering differs from software engineering in one critical respect: code gets a great deal of deterministic feedback from compilers, tests and execution, while a data engineering program can run successfully and still produce the wrong result. Errors like these raise no error message and are often discovered only months later, during reconciliation. A model that hallucinates does not reduce them; it makes them arrive faster and in greater numbers.
Investment is rising, but resources remain tight
In Deloitte's 2025 CDO survey, 54% of respondents had expanded their data teams in the previous year and 63% expected further growth; 48% still cited budget and resource limits as a key challenge to AI adoption.
Maintenance consumes half of engineering time
Fivetran's survey of 500 data and technology leaders at large enterprises found that engineering teams spend an average of 53% of their time maintaining data pipelines.
Fivetran — Enterprise Data Infrastructure Benchmark 2026 · 500 large-enterprise leaders ↗
AI is concentrated in coding
In dbt Labs' survey of 363 practitioners and leaders, 72% prioritized AI-assisted coding, while only 24% prioritized AI-assisted pipeline management, including testing, observability and quality control.
dbt Labs — State of Analytics Engineering 2026 · 363 respondents ↗
Quality and governance remain foundational
In BARC's global survey of 1,795 participants, data quality management ranked second and data governance fourth. AI and automation have not displaced these foundational priorities.
BARC — Data, BI & Analytics Trend Monitor 2025 · 1,795 participants ↗
Today's data engineering was designed for human engineers; handed to an agent, its complexity becomes an almost unbounded action space. LongData's view is that whether an agent can take on data engineering is decided not by the model itself, but by the environment it works in.
Design paradigm
Three separations: compute–storage, compute–program, compute–semantics
Compute–storage separation is proven across the industry; compute–program and compute–semantics separation are put forward by LongData as a paradigm. SQL drew a stable, precise boundary between the program and the compute engine. LongData's intent draws another between the business and whoever implements: the business defines what a correct result is, AI writes the implementation, the engine does the computing, and the platform issues the verdict.
Compute–storage separation
Compute is no longer bound to a particular data store. Storage and compute scale independently; this is now the basic architecture of the modern data platform.
Compute–program separation
All computation moves out of applications and data pipelines into databases and compute engines. The program acts only as glue and coordination, and does no computing.
Compute–semantics separation
Business requirements, including goals, definitions, business logic, rules, code values and acceptance criteria, move out of SQL, scripts and execution code. Implementations can be regenerated and replaced; business semantics become a long-term asset.
With compute separated from the program and from semantics, the data engineering program becomes far simpler. That is why an agent can generate a project's jobs reliably, and why it can move from helping to write pipelines to completing data engineering.
Product
LongData is made of five parts
LongData is not AI added on top of a traditional ETL system. It is a data engineering foundation redesigned the simple way, on which agents do the development.
Deterministic execution kernel
Common mechanisms such as incremental loading, windows, concurrency, idempotency, deletes, failure recovery, bulk processing, run records and pre-run checks are implemented once by the framework; every run behaves deterministically and can be reproduced.
Intent
The machine-readable form of the business requirement: translated by the agent from the business's requirements document, independent of the implementation, written to an open standard and versioned.
Agent loop
Starting from the business's requirements document, the agent writes, runs, verifies and corrects until it delivers a complete project.
Skills
The platform's engineering knowledge and the enterprise's own business knowledge, supplied to the agent once a person has signed them off. Once signed, the enterprise's business knowledge is reused across all of its projects.
Evidence
Every development, run, verdict and sign-off leaves a record automatically, forming an auditable evidence chain.
Value
Two core values, and the deterministic verification that makes them safe to adopt
Core value
Jobs run faster
Performance is decided once, at design time, and the agent writes within that design. Batch jobs can fall from hours to minutes, and pipelines run 24/7 in continuous micro-batches with latency in seconds.
Core value
Development takes fewer people
Requirements analysis, writing, testing, correction and reconciliation, work that used to take weeks of scheduled engineering time, is done by agents in the development environment. A business analyst submits a requirements document and receives a complete, verified project.
Guarantee
Every result is verified
The business sets the acceptance criteria and the platform issues the verdicts; the agent cannot change how they are reached. If a pre-execution check fails, the job does not run and no data is changed; after execution, the platform judges the data this run processed, criterion by criterion.
Delivery
From a requirements document to a complete project
The agent loop lets a model that hallucinates converge reliably within a bounded budget: starting from the business's requirements document, the agent delivers a complete project that is verified and ready to run in production.
Requirements document
A business analyst writes the goals, definitions, code values and sample cases in business language, with no template to follow. The requirements document is signed by people and is the project's semantic source.
Development and verification
The agent translates the requirements document into the project's overall intent and decomposes it until each goal can be met by one job. For each job it selects a tool or generates an implementation, runs it in the development environment, reads the verdict and corrects the fault where it lies.
Escalation of semantic gaps
Faced with a code value nobody defined or a measure nobody explained, the agent does not guess: it stops and raises a ticket for the business to answer. Schema changes go to the DBA through tickets.
Sign-off and production
The platform freezes every file the delivery runs and replays the whole project from the start on the frozen files; the business signs once, on the complete evidence chain. Production runs only the version that was signed off and promoted, fully deterministic and with no AI involved.
Run verdict
Every run is judged item by item on the data it processed; if a blocking criterion does not hold, the result is marked failed.
- PASS
schema_compatiblebefore execution: the target holds every source value without loss
- PASS
source_fully_readevery source row in the window was read
- PASS
row_count_balancedsource read = target written + deleted + rejected + filtered
- PASS
rejects_captured_torejected rows are stored with their reason
- FAIL
codeMapa source value outside the code table, escalated to the business as a semantic gap
Run guarantees come with each kind of job; business criteria are written in the intent. The platform issues the verdicts: an agent can read them but cannot change how they are reached.
Platform capabilities
Data engineering capabilities built into the platform
Agents are reliable because their action space is bounded: the mechanisms of data engineering with the most detail and the most room for error are built into the platform as production-proven capabilities.
Sync and loading
Full and incremental sync, merge writes by primary key, and bulk loading across systems. Rows deleted at the source are marked or removed in the target as the intent declares.
Continuous running
Pipelines run 24/7 in continuous micro-batches, and each micro-batch picks up the latest changes at the source.
Transformation
Code-value mapping, expressions, cross-table joins and aggregation are pushed down to the data engine; processing that SQL cannot express is written as separate processing code.
Reconciliation
From row counts to row-by-row comparison, at a depth you choose. The two sides can sit in different systems, and reconciliation can also audit pipelines not built on this platform.
Metadata catalogue
Collects the databases, tables and columns of every data source automatically and keeps them current, as the source of truth for agent authoring and platform checks.
Schema changes
Tables are always created and altered by the DBA. Before writing, the platform checks that the target can hold every source value without loss.
Pipelines
Jobs are composed into pipelines that run by choreography: adding or removing a node does not affect the others, running needs no central scheduler or external coordination service, and pipelines can move across engines and clouds.
Data engineering skills
The platform installs with a full set of data engineering skills, distilled from years of practice, that guide the agent as it plans, designs and writes every job.
Governance, lineage and data assets
The records governance needs are produced in every normal run. Data lineage needs no manual registration: every batch of data traces back to the intent, implementation and run that produced it. Metadata, semantic, evidence and capability assets accumulate as the platform is used.
Verification
Every run is judged
LongData does not define trust as AI claiming its results are correct. Trust means a data artifact can prove it meets a set of requirements the enterprise has explicitly declared, versioned and authorised.
Irreversible damage is stopped before execution
If a write would truncate, change a type or put a null into a non-null column, the job is refused before it runs and the column at fault is named.
Business criteria and run guarantees
Every run is judged on the data it processed: business criteria are written in the intent, and run guarantees come with each kind of job.
Reconciliation at the depth you choose
From matching row counts, column totals and null counts, through one-to-one primary keys, to row-by-row comparison. How far a result can be trusted becomes a measurable property that can be delivered.
Verification can be strengthened, and weakening leaves a record
Adding acceptance criteria only raises confidence; deleting a declared criterion requires a new sign-off, and switching off a run guarantee must be justified and listed in the report.
Trust does not mean never being wrong. It means always knowing how far the current result has been verified.
Who it is for
Built first for the business analyst
A business analyst holds both the business semantics and the technical understanding: the definitions and rules as well as the tables and columns. With LongData, the business analyst no longer has to hand the requirement over to a data engineer.
Business analysts and data analysts
Write the requirements document in business language, with no SQL, and receive a complete, verified delivery.
Data engineers
When an agent cannot complete development on its own it raises a ticket. A data engineer steps in, finds the problem, adds or improves a skill, and helps the agent finish the work.
DBAs
Table structures and the metadata catalogue stay under the DBA's control. The platform submits the changes it needs, with a proposed solution, to the DBA and never executes them itself.
Data governance and compliance leads
The metadata catalogue, business semantics, verification conclusions and the records of development and runs accumulate automatically in daily operation, ready to be used for recognising data assets and for audit.
AI platform owners
A platform interface that any agent can drive and learn from with no human documentation, and that joins the enterprise's existing agent systems as MCP tools.
What this division of work implies
The business analyst is both the author of the requirement and the one who signs off the delivery, so the agent only needs to be an accelerator, not an infallible decision-maker. An agent that is right most of the time, and whose other results are stopped on the spot by the acceptance criteria and handed back to a person, is already useful under this division of work.
Deployment, security and integration
Data and compute stay in the customer's databases
Data stays within its domain
Storage and large-scale computation remain with the customer; the platform moves only small data such as intents, verdicts, records and metadata. Data stays within its domain, with no egress fees and no lock-in. Deployment can be on-premises, hybrid or multi-cloud.
No model lock-in
Use frontier models in the cloud, regionally hosted model services or models deployed on premises, and choose a different model for each stage of development.
Four ways to integrate
Call it directly from Python, connect it to existing agents as MCP tools, call it from other systems over HTTP, or operate it through the web console. All four use the same implementation and reach the same conclusions.
Security principles
Credentials never enter a project, read-only sources are never written to, schema changes are made only by the DBA, verdicts are beyond the agent's influence, and every development and run is recorded.
Get in touch
Let's talk.
If your organisation runs data delivery in-house, builds data systems for clients, or is considering an investment, we would like to hear from you.